htdemucs
Standard on this site
- Vocals
- Drums
- Bass
- Other
Or vocals and instrumental
- SDR
- 8.80 dB
- Time
- 20.6 s
- Credits
- 4
2 stems: 13.1 s, 3 credits
Pick it for: Most songs, karaoke, first listens
Model guide · htdemucs, htdemucs_ft and htdemucs_6s
Demucs v4 ships three pretrained Hybrid Transformer models, and Demucs.net runs all of them on cloud GPUs. Compare their stems, quality, speed and cost.
15 free credits every month · No card needed · Uploads auto-deleted
htdemucs, htdemucs_ft and htdemucs_6s are all Demucs v4 Hybrid Transformers trained on MUSDB18-HQ plus 800 songs. Time and credits are for a 4-minute song here.
htdemucsStandard on this site
Or vocals and instrumental
2 stems: 13.1 s, 3 credits
Pick it for: Most songs, karaoke, first listens
htdemucs_ftBest quality on this site
Or two; four fine-tuned models inside
2 stems: 5 credits
Pick it for: Acapellas and bass lines you will publish
htdemucs_6s6 stems on this site
Also splits four or two
No SDR published
Pick it for: Guitar parts; piano with care
SDR: signal-to-distortion ratio on the MUSDB HQ test set, from Table 1 ofHybrid Transformers for Music Source Separation(Rouard, Massa and Défossez, 2022) and theDemucs README. Time: GPU time on an Nvidia A100, September 2026, 320 kbps MP3 output.
A Creative Commons song split into four stems with htdemucs on this site. Solo each stem before you pay extra for htdemucs_ft or htdemucs_6s.
htdemucs is the first Hybrid Transformer Demucs model and the default of the demucs command, trained on MUSDB plus 800 songs.
It splits a mix into vocals, drums, bass and other, or into vocals and instrumental, which the project's documentation calls karaoke mode.
In the paper's Table 1 it scores 8.80 dB, ahead of Hybrid Demucs v3 on the same data at 8.34 dB and Spleeter at 5.91 dB.
Pick it when: you want stems fast, for a karaoke track or a practice mix, or you are not sure which model suits the song. Run it first.
htdemucs_ft is htdemucs fine-tuned once per source: four copies of the model, each trained further on drums, bass, other or vocals.
All four run on every song, which is why the README warns it "will take 4 times more time but might be a bit better".
That 4x is model time. End to end here it took 1.56 times as long, because MP3 encoding costs the same for both models.
Pick it when: the vocal or the bass is the stem you will publish, or htdemucs left bleed you can hear. For a party karaoke track, skip it.
htdemucs_6s adds guitar and piano to vocals, drums, bass and other, the only Demucs model with those two stems. It runs the 6 stems option here.
Demucs 6 stems means htdemucs_6s; ht_demucs6s is the same model spelt differently.
The README says plainly that "the piano source is not working great at the moment", and no SDR is published for it.
Pick it when: you need the guitar on its own, to learn a part or sample a riff. Check the piano stem before you rely on it.
Our test: the rock song in the demo, which has no piano
Same architecture, training data and outputs. The trade is 0.2 dB overall, mostly in vocals and bass, for 1.56 times the time and 1.6 times the credits.
The cost, for a 4-minute song
| htdemucs | htdemucs_ft | |
|---|---|---|
| Time, 4 stems | 20.6 s | 32.0 s |
| Credits, 4 stems | 4 | 7 |
| Credits, 2 stems | 3 | 5 |
Our rule: run htdemucs first. If the vocal stem carries traces of the drums or the bass wobbles, rerun the song on htdemucs_ft. Most songs never need the second pass.
htdemucs, 2 stems
3 credits and about 13 seconds. Our karaoke maker opens in that mode.
htdemucs_ft, 2 stems
Its largest gains are on vocals and bass.
htdemucs, 4 stems
Or htdemucs_ft if the bass stem will be published. The stem splitter opens with four stems selected.
htdemucs_6s
The only model with those sources. Listen to the piano stem before you trust it.
htdemucshtdemucs_6s
htdemucs_6s for a guitar line. htdemucs_ft adds nothing you will hear at practice volume.
htdemucs
The default for a reason, and the cheapest. Move up only when you hear why.
All score lower than the Hybrid Transformers on the same benchmark, 7.7 dB for Hybrid Demucs v3 in the README's table, so Demucs.net runs only htdemucs, htdemucs_ft and htdemucs_6s.
hdemucs_mmimdxmdx_extramdx_qmdx_extra_qQuick answers on htdemucs, htdemucs_ft and htdemucs_6s: their names and what they need to run. Anything else? Get in touch .
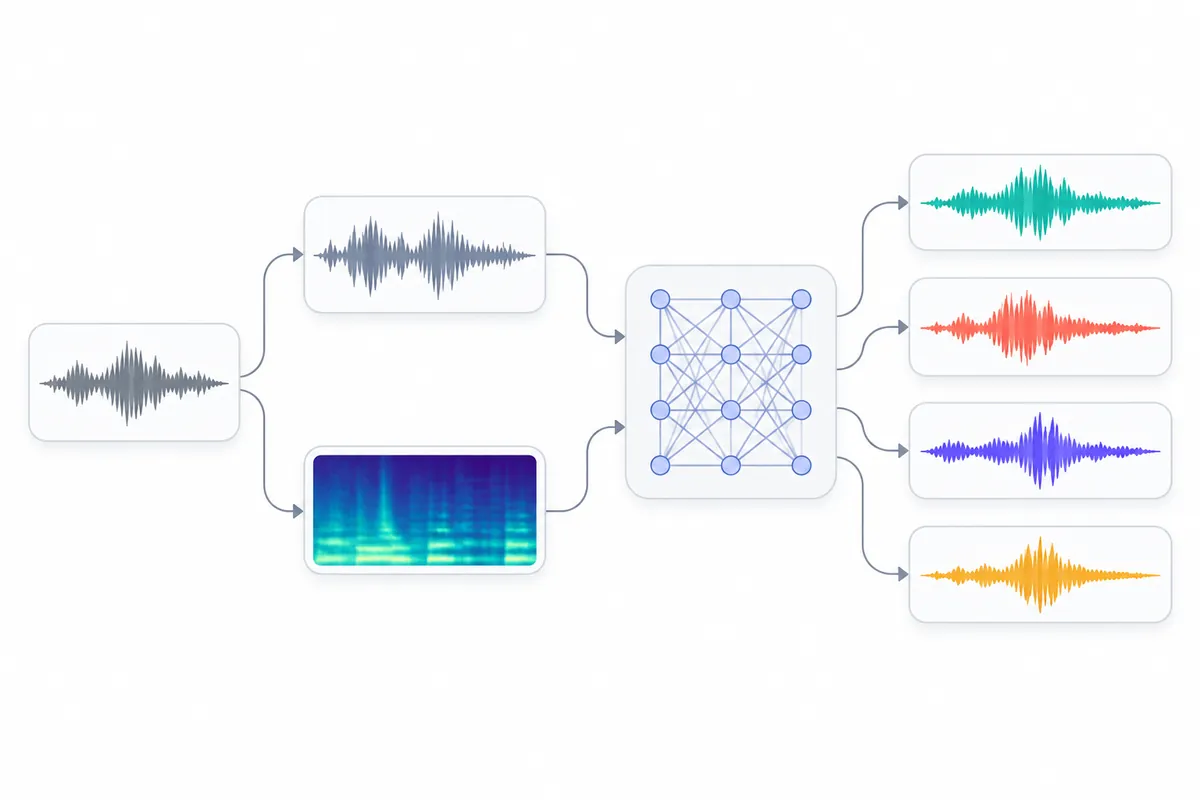
Hybrid Transformer. Demucs v4 replaced the innermost layers of Hybrid Demucs (v3) with a cross-domain Transformer encoder that reads the waveform and the spectrogram at once; with 800 extra training songs, the paper puts it 0.45 dB of SDR ahead of Hybrid Demucs.
In model time, roughly, because four fine-tuned models run instead of one. End to end here htdemucs_ft is 1.56 times slower, 32.0 against 20.6 seconds for a 4-minute song, since encoding the MP3 stems takes the same time either way.
None; they are two spellings of the same six-stem model. Its name in the Demucs repository is htdemucs_6s, and it is the model behind the 6 stems option here.
htdemucs_ft: 9.20 dB on vocals in the paper’s Table 1 against 8.93 dB for htdemucs. For karaoke, where the instrumental matters more than the vocal, the standard model is usually enough; htdemucs_6s is not the tool for this, its extra sources are guitar and piano.
Not reliably. The authors say the piano source "is not working great", and in our own test on a song without piano the piano stem came back empty while the guitar stem was solid. Use htdemucs_6s for guitar, audition the piano stem before you rely on it, and use htdemucs or htdemucs_ft when you need neither.
Yes. Every signed-in account can pick htdemucs, htdemucs_ft or htdemucs_6s; they differ only in credits per minute of audio, at 1, 1.6 and 1.3 times the standard rate.
Running them yourself, the README asks for at least 3 GB of GPU memory, about 7 GB with default settings; on a CPU expect roughly 1.5 times the length of the track. Here htdemucs, htdemucs_ft and htdemucs_6s run on cloud GPUs, so none of that applies.
The original repository says it is not maintained anymore, since its author left Meta; a fork carries important bug fixes. The pretrained models are unaffected: htdemucs, htdemucs_ft and htdemucs_6s are finished weights, and they are what this site runs.
Upload a song, pick htdemucs, htdemucs_ft or htdemucs_6s, and hear the difference yourself. 15 free credits every month, no card needed.
Split a Song Free